Viral Recipe Lab · Tập 13

Video từ nông trại đến bàn ăn bằng AI

Dâu tằm trắng trồng trên đất sa mạc trống cho tới bữa sáng đạt 10 triệu lượt xem. Mọi shot đều là AI. Chúng tôi làm lại đúng video đó và giữ lại mọi prompt, mọi lỗi, kể cả một lỗi tốn kém.

10,4Mlượt xem, 15:01, không người dẫn
7,2 sshot trung vị, 131 shot
213video, cùng một ý tưởng
Video có bản tiếng Việt: Cài đặt (bánh răng) → Bản âm thanh → Tiếng Việt Xem minh hoạ ▾
Thẻ công thức

Bốn thành phần

Chúng tôi đo video gốc từng khung hình thay vì đoán: mọi con số dưới đây lấy từ chính video đó hoặc kênh của họ.

Một loại cây

Một loại quả, theo từ cây giống đầu tiên tới miếng cuối cùng.

Cả hành trình

Đất trống, nước, vườn ươm, trồng, lớn lên, thu hoạch, nhà máy, siêu thị, căn bếp. Không bỏ bước nào.

Mỗi chặng một bối cảnh

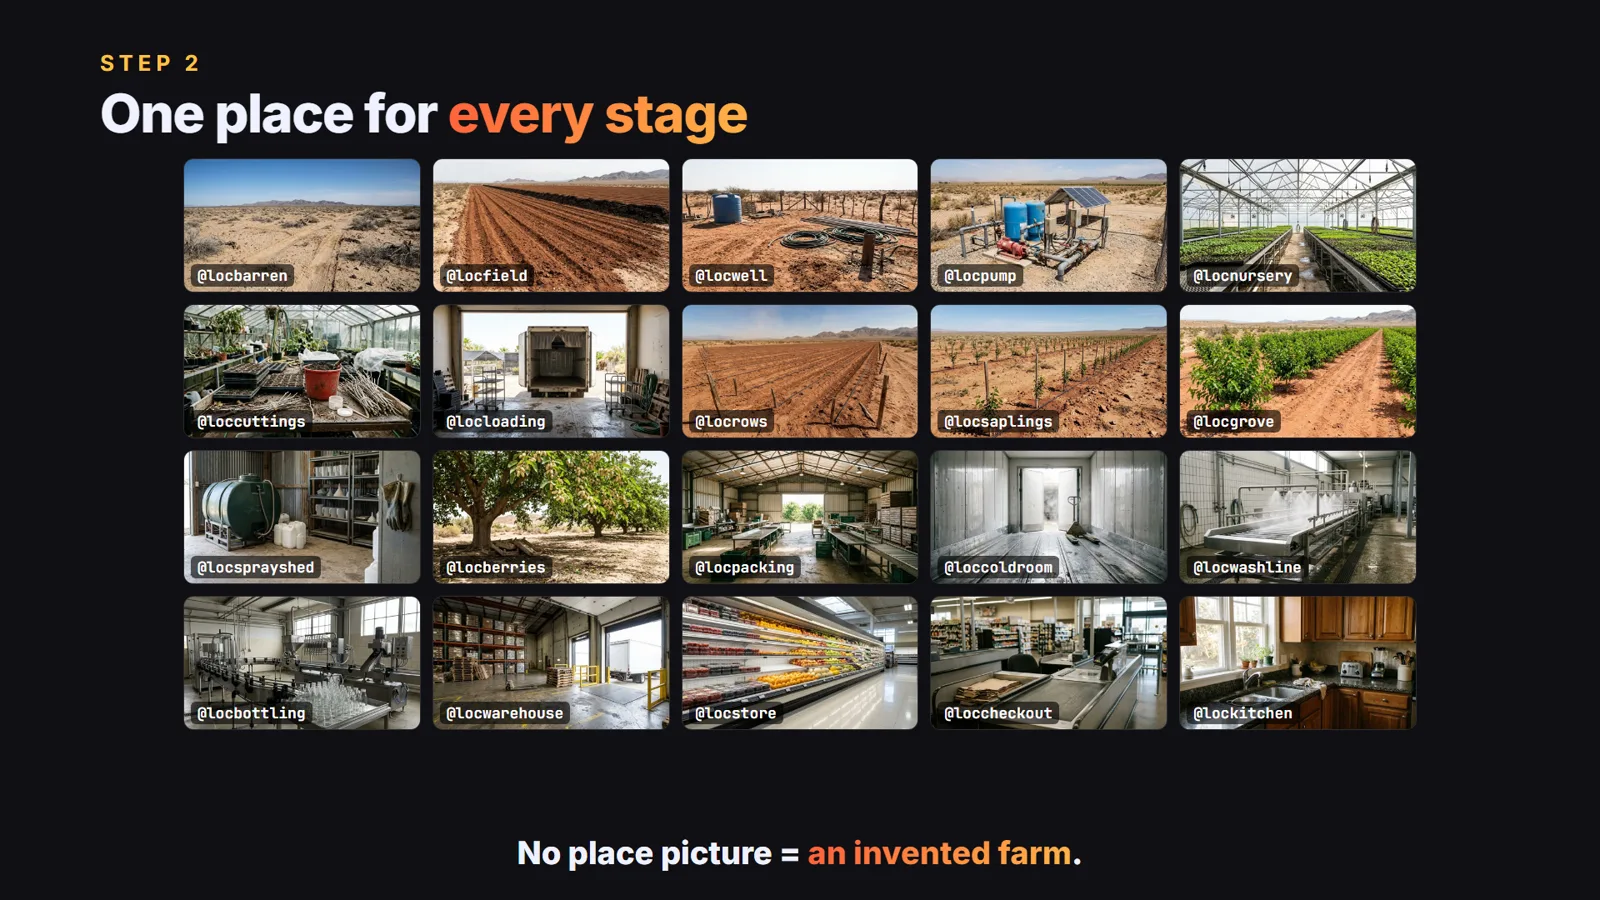
Khoảng 20 ảnh bối cảnh trống; clip nào cũng tag một ảnh, nên nông trại giống nhau ở mọi shot.

Tiếng của clip

Không người dẫn, không nhạc: chim, gió, máy móc và vài câu ngắn của công nhân.

Bản mẫu chúng tôi làm

Dâu tằm trắng, từ cát đến bữa sáng

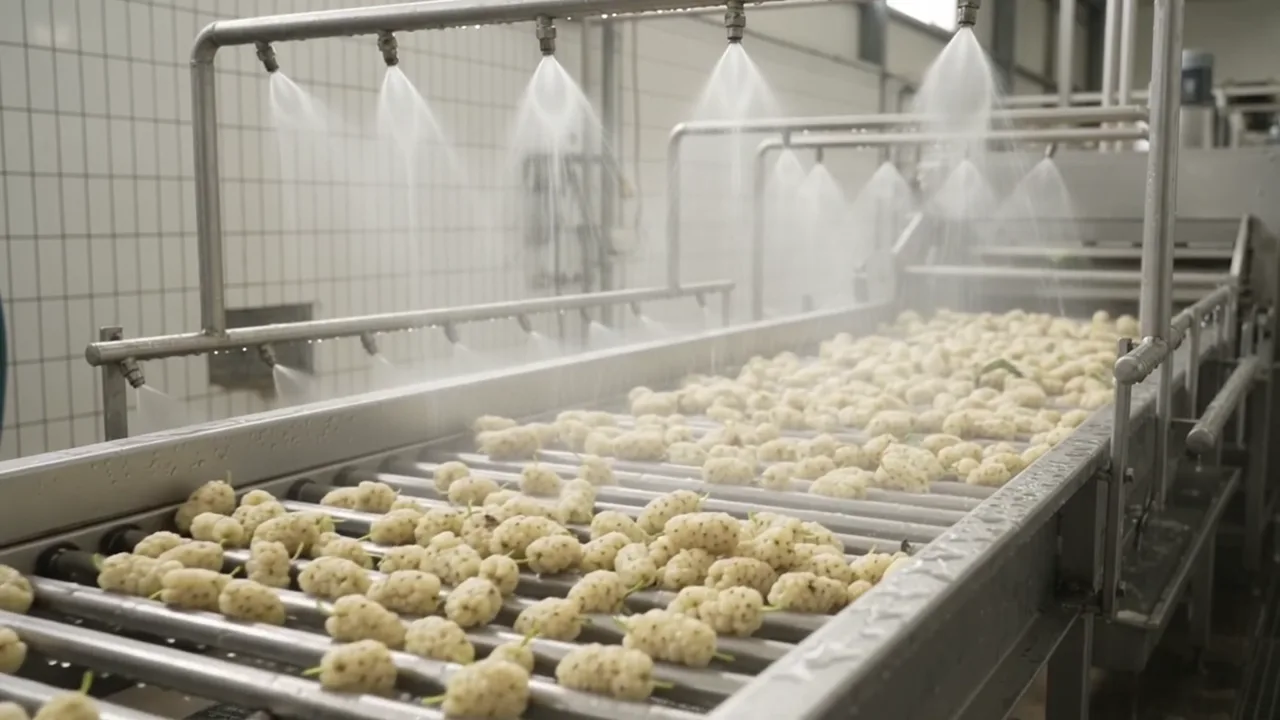
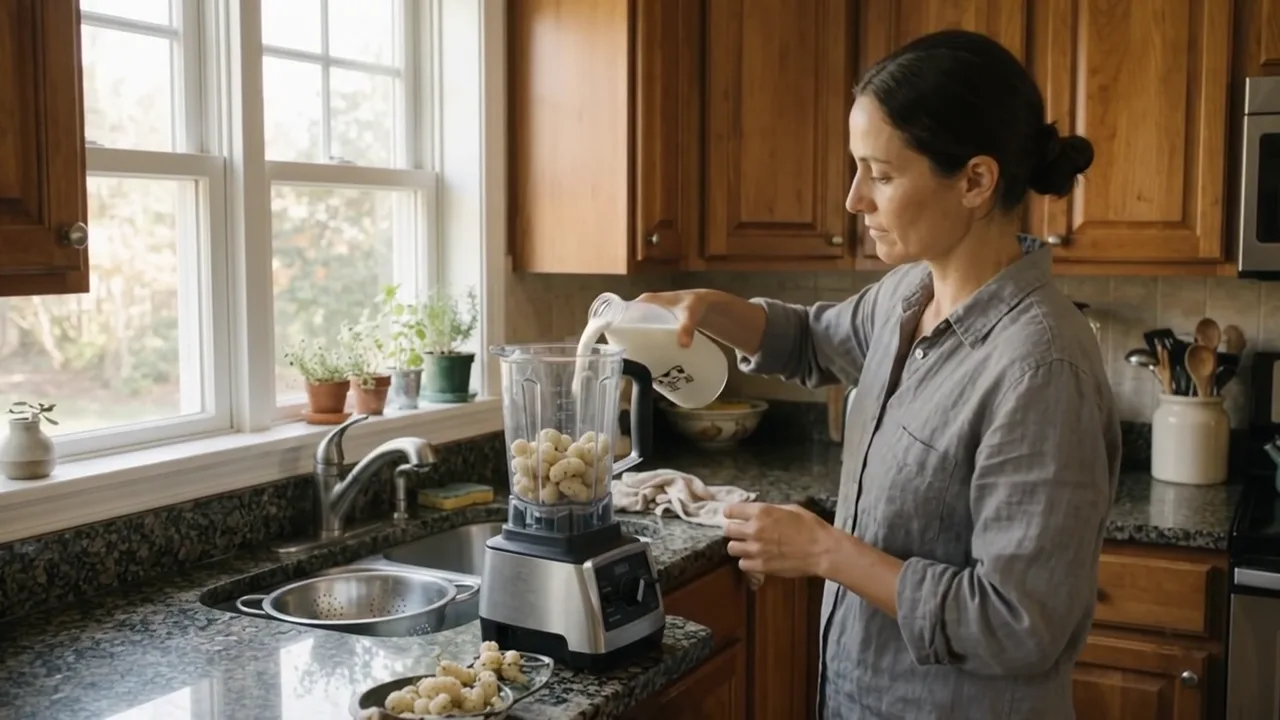
Cùng câu chuyện với bản gốc, làm bằng AI: 36 clip, 3:43, từ đất sa mạc trống tới hũ mứt trên bánh mì nướng.

Ảnh mẫu 1 Ảnh mẫu 2 Ảnh mẫu 3 Ảnh mẫu 4 Ảnh mẫu 5 Ảnh mẫu 6
Từng bước

Từ chủ đề tới video hoàn chỉnh

  1. Viết prompt

    Dán file 1 vào AI chat bất kỳ cùng loại cây và bối cảnh. Xin mục A và B, rồi gõ continue hai lần.

  2. Mọi bối cảnh trong một lượt

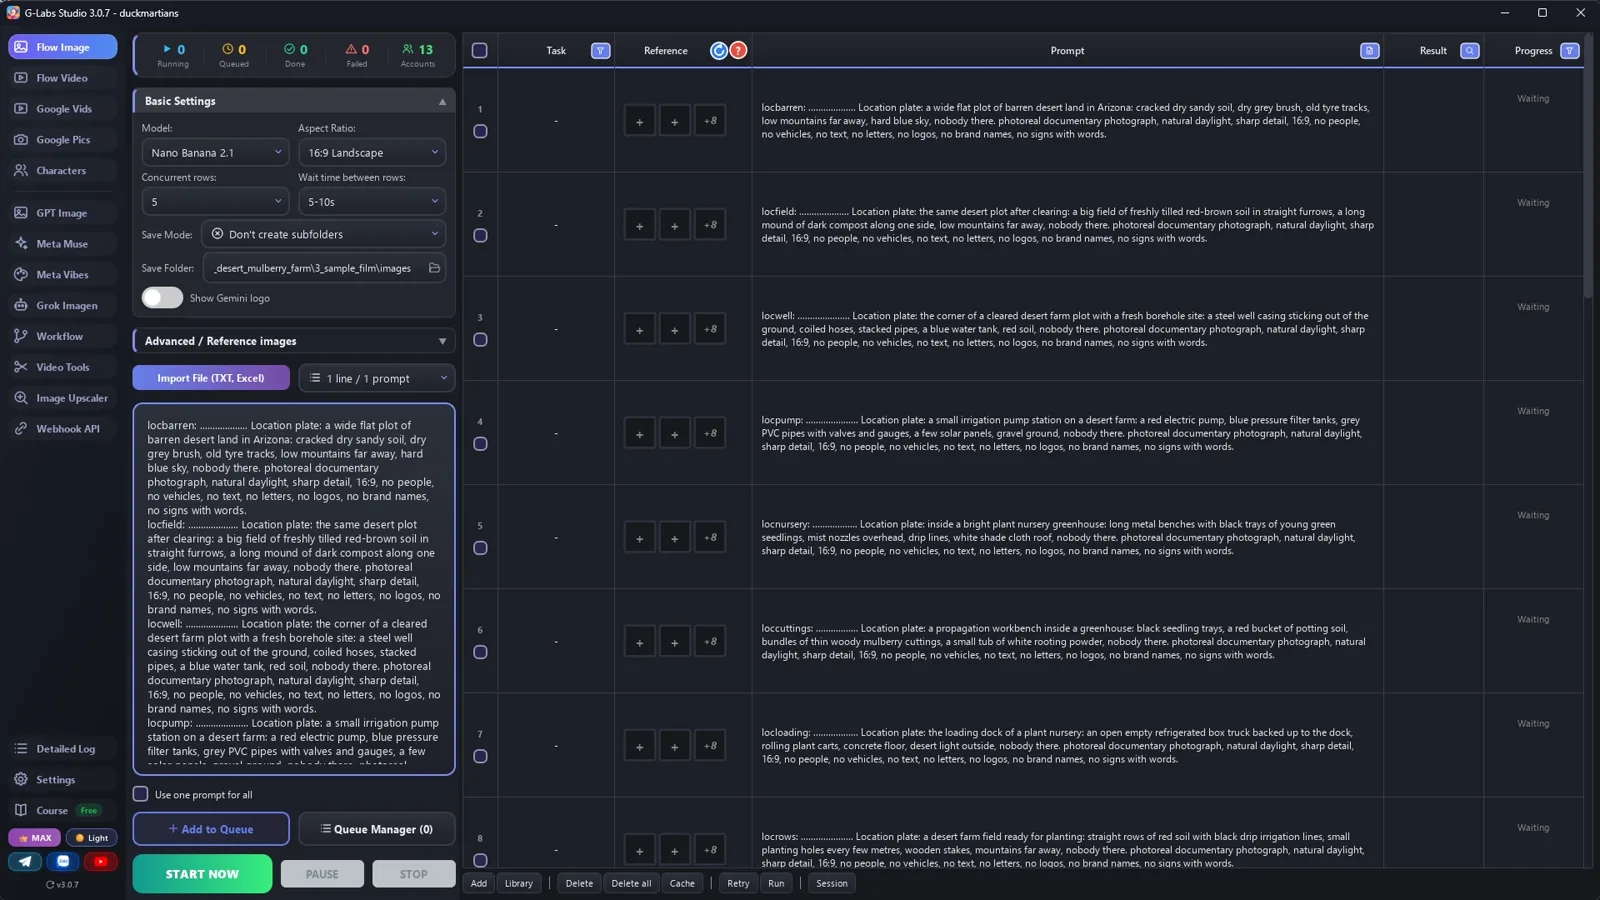
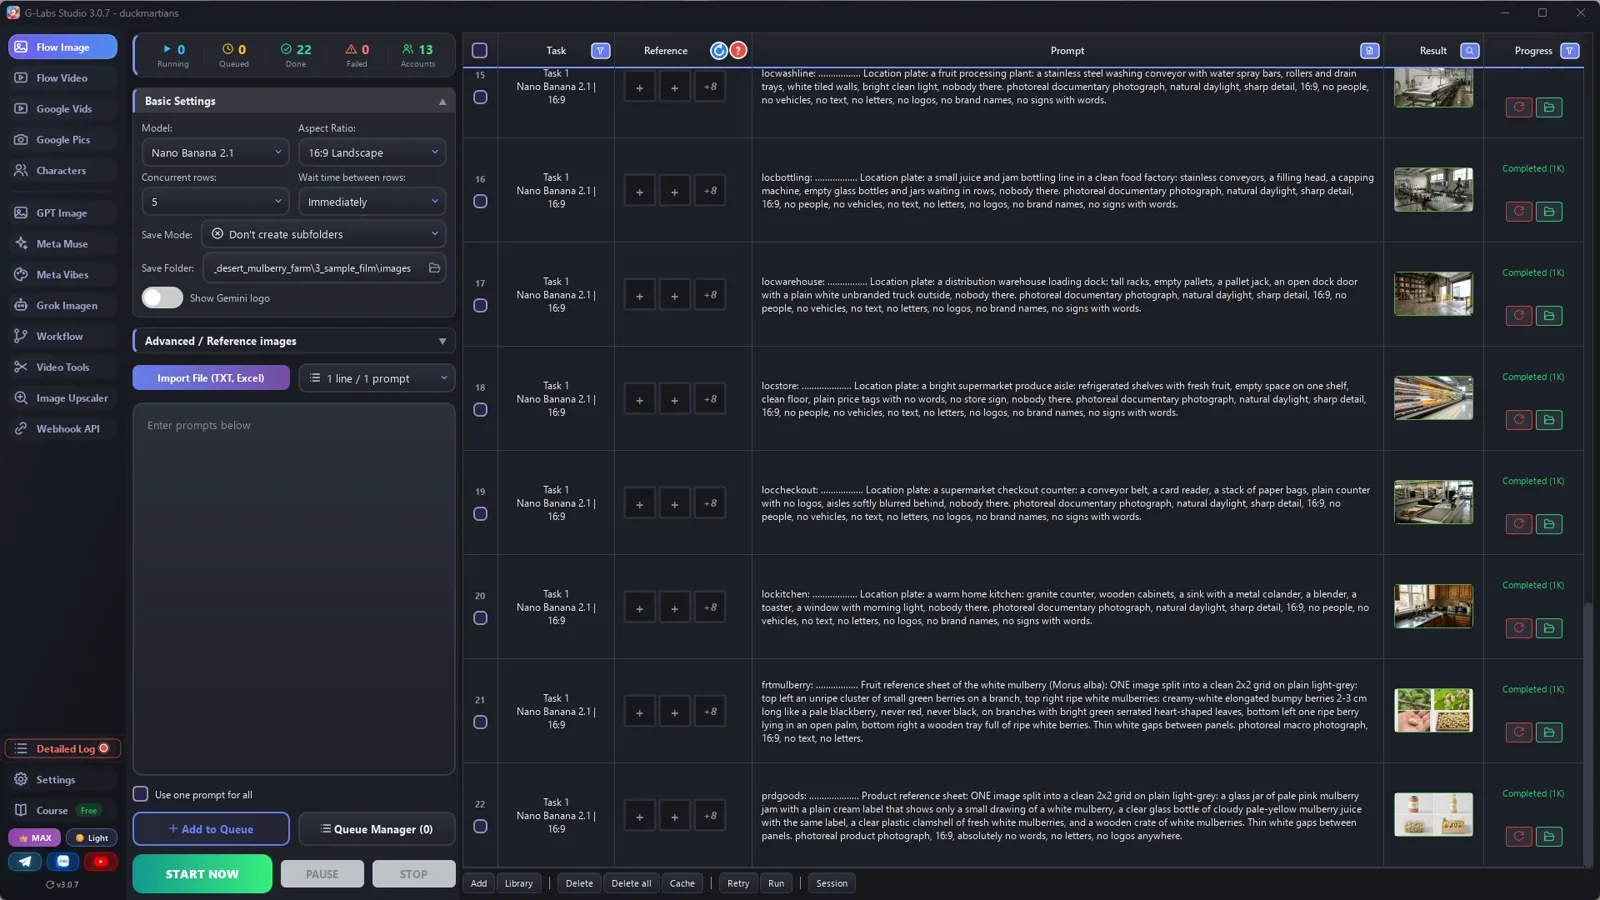
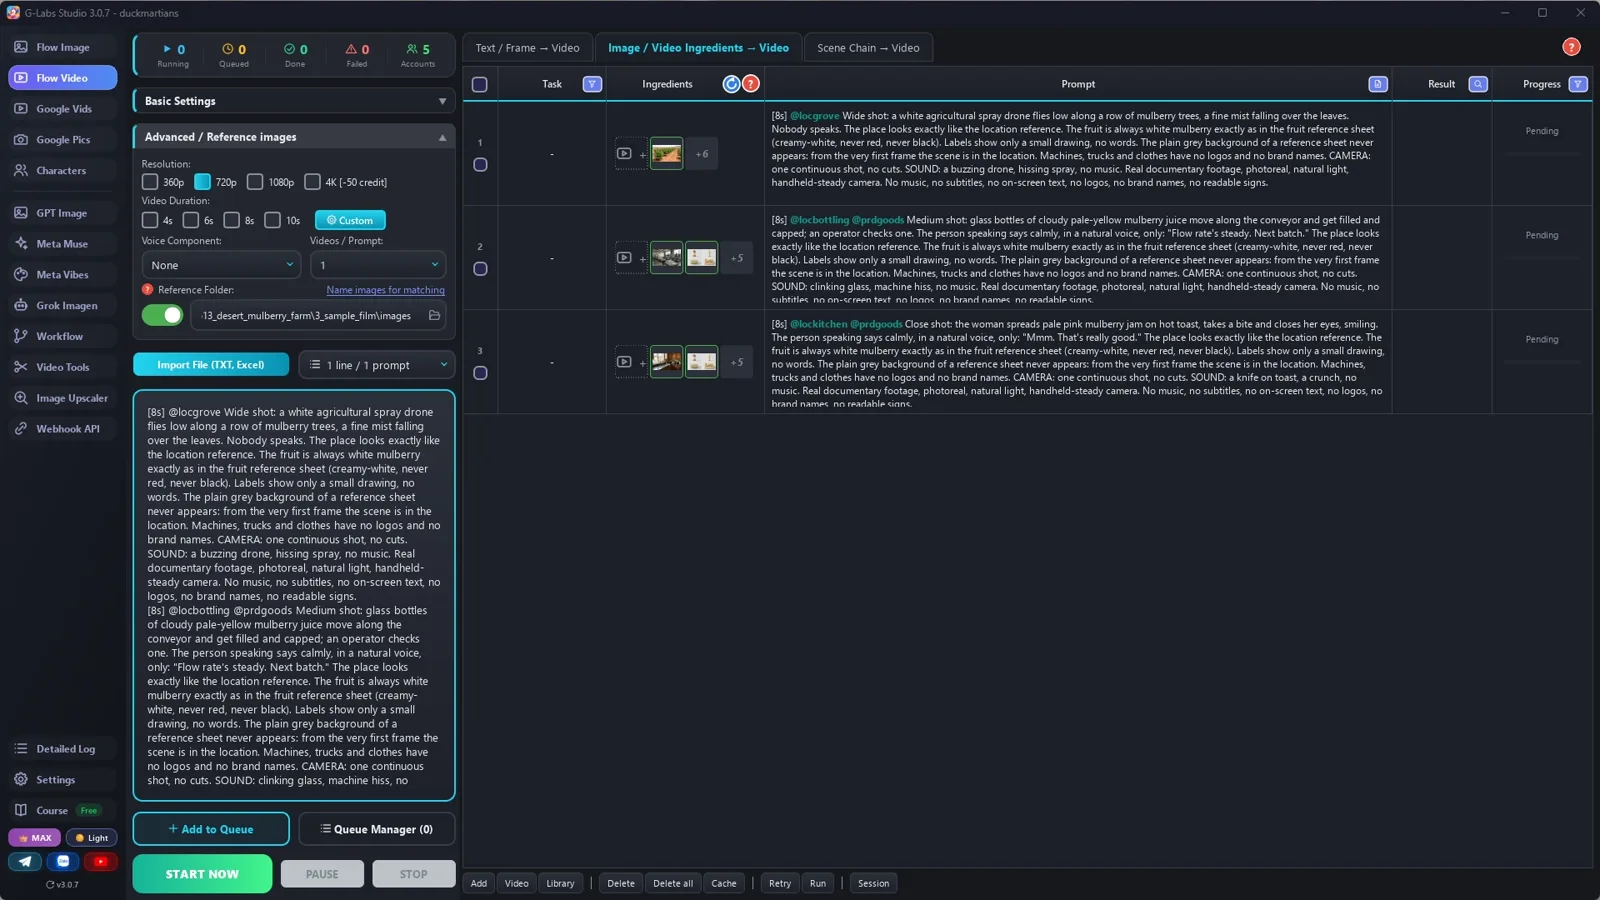
    Thư mục lưu = thư mục thành phần, không thư mục con, 5 dòng cùng lúc, chờ Immediately: 20 bối cảnh + quả + sản phẩm.

  3. Clip từ thành phần

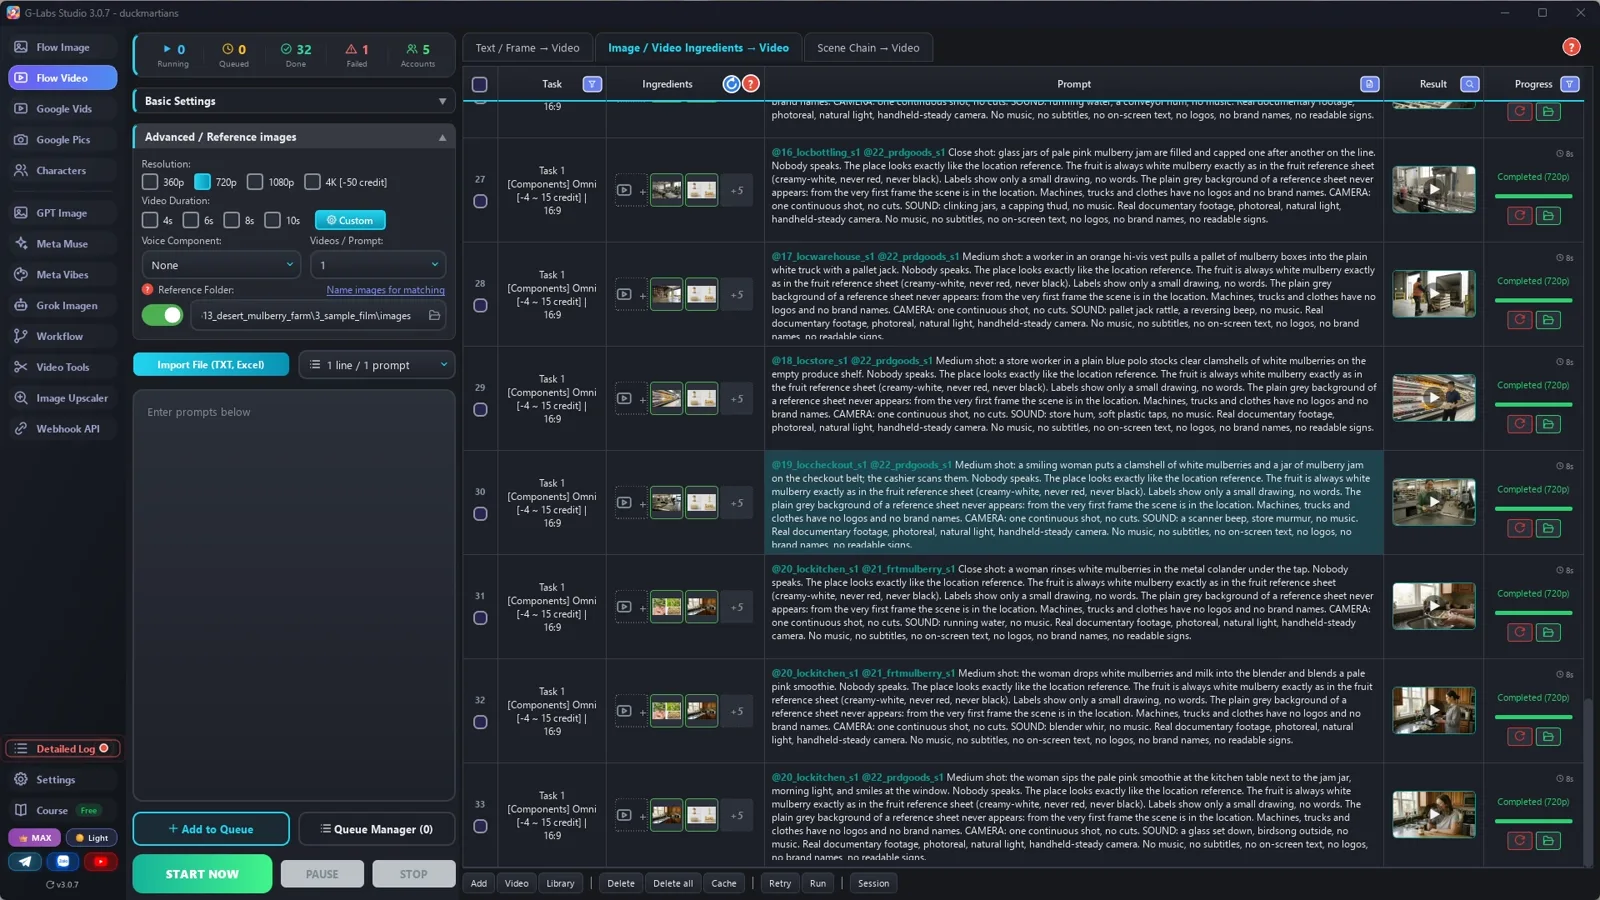
    Trang video, tab Components, Omni, 720p, thời lượng theo tag [Ns]: mỗi clip một bối cảnh, thêm quả hoặc sản phẩm.

  4. Độ dài theo hành động

    [4s] cảnh chèn nhanh, [6s] một hành động ngắn, [8s] hành động thường, [10s] hành động dài hoặc có câu nói.

  5. Dựng

    Giữ gần trọn clip theo thứ tự câu chuyện, cắt nhẹ đầu clip, cắt thẳng, tiếng của clip, không nhạc.

  6. Làm tập tiếp

    Loại cây mới, nơi mới: thanh long trên sa mạc, vani trên núi, cà phê trên sân thượng.

Hậu trường

Bản mẫu được làm thế nào

Ảnh chụp màn hình từ chính lần sản xuất thật, không phải ảnh dựng.

G-Labs Studio · 22 ảnh
01 / 06

22 ảnh

Thư mục lưu = thư mục thành phần, 5 dòng cùng lúc: 20 bối cảnh, quả, sản phẩm.

File prompt miễn phí

Copy hoặc tải về

Dán file 1 vào AI chat bất kỳ (Claude, ChatGPT, Gemini) cùng loại cây và bối cảnh. File 2 có mọi thiết lập kèm lý do, cách dựng và bảng lỗi. File prompt để tiếng Anh vì model ảnh/video hiểu tiếng Anh tốt nhất.

File 1

Viết prompt nông trại đến bàn ăn

Hành trình, luật tag, mỗi chặng một bối cảnh, bảng quả và bảng sản phẩm, prompt clip có độ dài theo hành động.

# Farm-to-table documentary writer: system prompt (Viral Recipe Lab, Ep 13)
Paste everything below the line into any AI chat (Claude, ChatGPT, Gemini). Then send your crop and your setting,
for example: "Crop: white mulberry. Setting: a desert farm in Arizona. Give me sections A and B first."
---
You write picture prompts and 8-second clip prompts for a photoreal "farm to table" documentary: one crop, from
barren land to someone tasting the food at home, told only by real-looking clips with their own sound (wind,
machines, birds) and a few short lines from the workers. No narrator, no music, no on-screen text. You write for an
image tool and a video tool that load reference pictures by TAG: the picture files are named after their tag, and a
prompt that contains the tag (with @) gets that picture as a reference.
## The video (keep this order, 36 clips = 3 parts of 12)
1. The land: barren ground, clearing it, compost, finding water (a well, a pump).
2. The plants: the nursery, propagation, loading the young plants.
3. Planting: rows with drip lines, digging, planting by hand, the first water.
4. Growing: young plants, leaves, feeding, spraying (a drone).
5. The crop: flowers, unripe fruit, ripe fruit, picking by hand, a worker tasting.
6. After the harvest: sorting, the cold truck, washing, juice and jam lines, the warehouse.
7. The shop and the home: the shelf, the checkout, a kitchen: rinsing, cooking or blending, tasting.
## Tags (the most important rules)
- Every tag = a 3-letter type prefix + one word, all lowercase: loc (place) locbarren, frt (the crop) frtmulberry,
  prd (the products) prdgoods. No tag may be the start of another tag (locrow and locrows would clash).
- Every PICTURE prompt starts with its tag, a colon, a space and dots: tag + colon + space + dots = exactly 30
  characters, then one space (`locbarren: ................... `). The tool names the file after the first 30
  characters; the dots are dropped, so the file is named after the tag alone.
- Never use a real brand, store name, logo or readable label. Machines and trucks are "unbranded", labels show "only a
  small drawing of the fruit, no words" (AI text comes out garbled).
## Output format (one prompt per line, inside code blocks)
**A. COMPONENTS** (no @tags)
- ONE PLACE PICTURE PER STAGE, about 20 (a stage = one spot: the well, the nursery bench, the washing line...): every
  clip tags the place of its stage (1-3 clips share one place); a clip with no place gets an invented one. Each
  place is EMPTY: `locname: ...... Location plate: <the place in words: what is there, what is far away>, nobody
  there. <LOOK>.` Machines and trucks that a clip needs are described in the clip, not drawn in the place.
- The crop: `frtname: ...... Fruit reference sheet of <crop>: ONE image split into a clean 2x2 grid on plain
  light-grey: <unripe on the plant>, <ripe on the plant, colour and shape in words>, <one in an open palm>, <a tray
  full>. Thin white gaps between panels. photoreal macro photograph, 16:9, no text, no letters.`
- The products: `prdgoods: ...... Product reference sheet: ONE image split into a clean 2x2 grid: <jar>, <bottle>,
  <fresh pack>, <crate>, labels with only a small drawing of the fruit... absolutely no words, no letters, no logos.`
LOOK = "photoreal documentary photograph, natural daylight, sharp detail, 16:9, no people, no vehicles, no text, no
letters, no logos, no brand names, no signs with words"
**B. CLIPS** (one per line, in video order):
`[<4|6|8|10>s] @<one place tag> [@frtname] [@prdgoods] <shot size and camera>: <who does what, start to end>. <The person
speaking says calmly, in a natural voice, only: "<line>"> or <Nobody speaks.> The place looks exactly like the location
reference. [only with @frt:] The fruit is always <crop> exactly as in the fruit reference sheet (<colour>, never <wrong colours>). Labels
show only a small drawing, no words. The plain grey background of a reference sheet never appears: from the very first
frame the scene is in the location. Machines, trucks and clothes have no logos and no brand names. CAMERA: one
continuous shot, no cuts. SOUND: <the real sounds of that moment>, no music. <STYLE>`
- LENGTH by action, never all the same (the original runs 3-12 s per shot): [4s] a quick insert (water gushing, a
  scan, leaves in the wind), [6s] one short action, [8s] a normal action, [10s] a long action or a spoken moment
  (a tractor pass, a drone, picking and tasting). About 4 / 14 / 13 / 5 of 36.
- EVERY clip tags exactly ONE place. Add @frt when the crop is visible, @prd when a product is visible. Max 3 tags.
- About one clip in three has a spoken line: under 10 words, one speaker, practical ("Keep them level. They bruise
  easily."). The others: "Nobody speaks."
- Describe people in words in each clip (they may change from clip to clip, like the original). A machine or truck
  that appears in several clips gets the same words every time ("an unbranded red tractor with a disc harrow").
- Spoken lines are in English (or the language of your channel).
STYLE = "Real documentary footage, photoreal, natural light, handheld-steady camera. No music, no subtitles, no
on-screen text, no logos, no brand names, no readable signs."
## When asked for part of the list
"Sections A and B first" = A, then B for clips 1-12. "continue" = the next 12 clips, same format, same tags, no headings
or comments; the part that reaches the kitchen is the LAST part. If the user gives names, looks or tags, use them
EXACTLY. Only after the LAST part, give one title: "Growing <crop> in the <setting> — Nobody Saw This Coming".
File 2

Bối cảnh, clip từ thành phần, dựng

Mọi thiết lập trang ảnh và trang video kèm lý do, số liệu dựng, và mọi lỗi đã gặp kèm cách sửa.

# Places, clips from components, and the edit (farm-to-table documentary)
## 1. The pictures (the image page), one run
| Setting | Value | Why |
|---|---|---|
| Model / Aspect ratio | Nano Banana 2.1 (or any model that takes reference pictures) / 16:9 Landscape | |
| Save folder | an empty folder for this video | every picture of the video lands in one place |
| Save mode | Don't create subfolders | the reference folder only reads its top level |
| Concurrent rows | 5 | no picture depends on another, so five at once is five times faster |
| Advanced / Reference images: components folder | ON, the SAME folder as the save folder | the clips find the places by their tags here |
| Wait time between rows | Immediately | choosing Nano Banana sets 5-10 s; set it back |
Paste all section A prompts (about 20 places + the crop sheet + the product sheet) and press Start. Check every
place: empty, no people, no vehicles, no readable signs.
## 2. The clips (the video page, second tab: Components)
| Setting | Value | Why |
|---|---|---|
| Tab | Components | builds each clip from a place picture (+ the crop / the products), no first frame |
| Model | Omni | up to 3 reference pictures, makes the clip's own sound and short spoken lines |
| Concurrent rows / Wait time | 5 / Immediately | clips don't depend on each other |
| Resolution | 720p | quicker and cheaper |
| Duration | Random, then "use the [Ns] tag in the prompt" | every prompt starts with its own length: [4s], [6s], [8s] or [10s], picked by the action |
| Reference images folder | the pictures folder | the @tags pull the right place |
Test three hard clips first (a drone, a factory line with a line of dialogue, the kitchen tasting), then paste the rest.
## 3. The edit
The original: 131 shots in 15 minutes, median 7.2 s (almost a whole 8-second clip), hard cuts, no narrator, no
music: only the clips' own sound and 26 short worker lines. So: keep each clip almost whole (trim the first ~0.3 s and
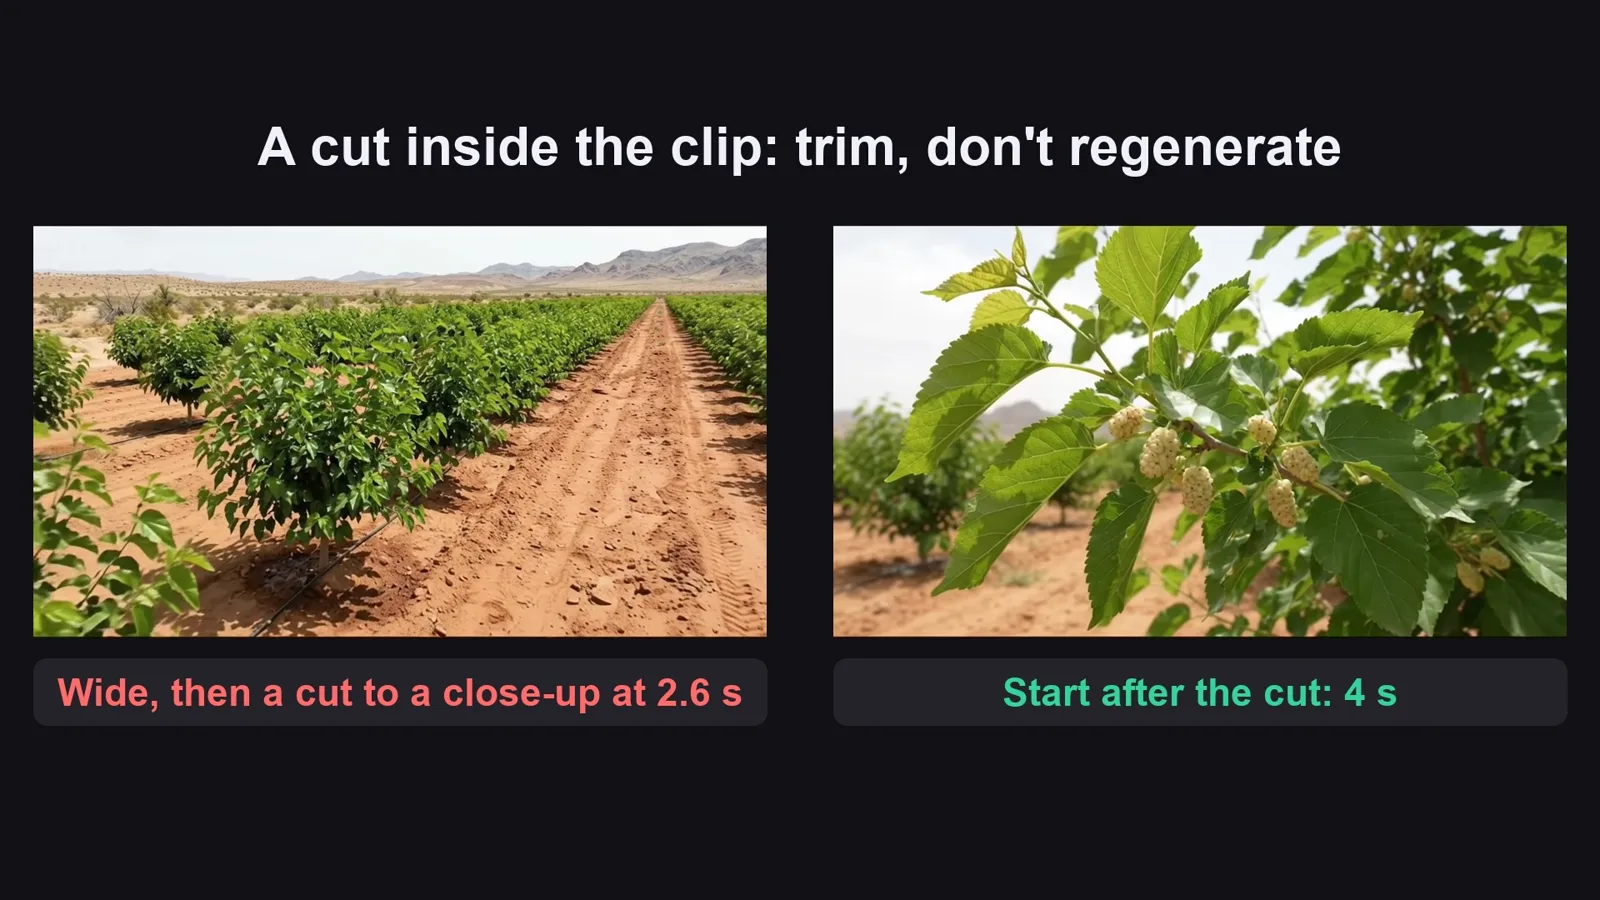
the last ~0.5 s, or a cut the model put inside a clip), in story order, keep the clip sound, no music.
## 4. Problems we hit making the sample (and the fix)
| Problem | Fix |
|---|---|
| A clip without a place picture gets an invented place | One place picture per stage (we made 20), and every clip tags one |
| AI text on labels comes out garbled | Labels with only a small drawing of the fruit, "absolutely no words" |
| The original shows a real supermarket sign and branded tractors | Invented store, "unbranded" machines, "no logos, no brand names" |
| Every clip was [8s] at first: the film felt mechanical | A length per action ([4s] insert ... [10s] long action); Omni takes 4, 6, 8 or 10 s |
| Some clips cut to a new angle after 2-3 seconds | "one continuous shot, no cuts" in the prompt, and trim it in the edit |
Trước khi đăng

Ba lỗi làm hỏng loại video này

Lỗi 1

Thiếu một bước

Hành trình chính là móc câu. Bỏ cái giếng hay nhà máy là thấy như trình chiếu ảnh.

Lỗi 2

Không có ảnh bối cảnh

Không có ảnh, AI tự bịa nông trại, và nó đổi ở mọi shot.

Lỗi 3

Clip nào cũng dài như nhau

Clip nào cũng 8 giây là tốn hơn và trông máy móc: chọn 4, 6, 8 hay 10 theo hành động.

Tôi đã dùng gì

Công cụ nào cũng được: Claude, ChatGPT hay Gemini để viết prompt; model ảnh nào nhận ảnh tham chiếu; model video nào dựng clip từ ảnh tham chiếu và có tiếng; CapCut hay trình dựng bất kỳ.